Generative Programming and Matrix Multiplication
Don Williamson, Jan 2006, don@donw.co.uk
This covers the implementation of a generic matrix multiplication function that can be extended to cover matrix/vector multiplication using the same type. The compiler used was VC8 and example code plus full assembly printouts are available in the download.
The matrix class is defined as follows:
template <int ROWS, int COLUMNS>
struct Matrix
{
	// Anonymous union providing two means of access
	union
	{
		float m[ROWS][COLUMNS];
		float v[ROWS * COLUMNS];
	};

	// Matrix accessors
	float operator () (int i, int j) const { return m[i][j]; }
	float& operator () (int i, int j) { return m[i][j]; }

	// Vector accessors
	float operator () (int i) const { return v[i]; }
	float& operator () (int i) { return v[i]; }
};
Matrices are stored row-major in memory and matrix/vector multiplication is done as:
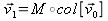
To allow the same multiplication function to work for both matrix/matrix and matrix/vector operations, vectors are stored as matrices with 3 rows and 1 column, as required by the above multiplication. There are no storage or access penalties for doing this. Our example is a 3x3 matrix and 3 element vector:
typedef Matrix<3, 3> Matrix_33;
typedef Matrix<3, 1> Vector_3;
The matrix multiplication function is:
template <int M, int N, int P>
Matrix<M, P> Multiply(const Matrix<M, N>& A, const Matrix<N, P>& B)
{
	Matrix<M, P> result;

	for (int i = 0; i < M; i++)
	{
		// If P=1 the compiler will optimise this loop out
		// entirely for release builds
		for (int j = 0; j < P; j++)
		{
			result(i, j) = 0;

			// Compiler unrolls this loop in release
			for (int k = 0; k < N; k++)
				result(i, j) += A(i, k) * B(k, j);
		}
	}

	return result;
}
This function is capable of being used for matrix/matrix multiplication and matrix/vector multiplication simultaneously. It also ensures that two input matrices match the multiplication dimension constraint that the number of columns in matrix A must be equal to the number of rows in matrix B. Conveniently this lets you annotate matrix/vector multiplication in code as it is on paper and disallows the use of vector/vector multiplication, unless you express the left vector as a row matrix.
Taking matrix/vector multiplication as our test operation (less output code), the generated code is pretty optimal; the 3 loops have been collapsed to only 1 inner loop:
004011F0  push        ecx
004011F1  fldz
004011F3  xor         ecx,ecx
004011F5  add         edx,8

004011F8  fst         dword ptr [eax+ecx*4]
004011FB  add         ecx,1
004011FE  fld         dword ptr [edx-8]
00401201  add         edx,0Ch
00401204  cmp         ecx,3
00401207  fmul        dword ptr [esi]
00401209  fadd        dword ptr [eax+ecx*4-4]
0040120D  fstp        dword ptr [esp]
00401210  fld         dword ptr [esp]
00401213  fst         dword ptr [eax+ecx*4-4]
00401217  fld         dword ptr [edx-10h]
0040121A  fmul        dword ptr [esi+4]
0040121D  faddp       st(1),st
0040121F  fstp        dword ptr [esp]
00401222  fld         dword ptr [esp]
00401225  fst         dword ptr [eax+ecx*4-4]
00401229  fld         dword ptr [esi+8]
0040122C  fmul        dword ptr [edx-0Ch]
0040122F  faddp       st(1),st
00401231  fstp        dword ptr [eax+ecx*4-4]
00401235  jl          Multiply<float,3,3,1>+8 (4011F8h)

00401237  fstp        st(0)
00401239  pop         ecx
0040123A  ret
The loops are restored in the debug version, allowing you to step through each part of your code.
You can squeeze more speed out of the inner loop in release builds by turning to generative programming. Take the following power function for example:
// Recursive power function evaluation
template <int V, int N>
struct Power
{
	enum
	{
		res = V * Power<V, N – 1>::res
	};
};

// Specialise for N=0 to set V^0=1 – this ends the compiler loop
template <int V>
struct Power<V, 0>
{
	enum { res = 1 };
};

int array[Power<2, 5>::res];
The result is a constant, evaluated at compile-time and generates no code. The example uses the result to declare and array of integers with 32 entries to demonstrate this.
Although the inner loop of the matrix multiplication function is already being optimised away by the compiler, it looks like something that can take advantage of the above technique. There are two problems stopping it:
Variable reads are involved which prevents the algorithm being fully compile-time.
The algorithm involves floating point arithmetic; floating point types cannot be used as template parameters.
However, it's worth seeing if we can get the compiler to generate the following code using recursive function calls, by inlining simple expressions:
result(i, j) = A(i, 0) * B(0, j) +
               A(i, 1) * B(1, j) +
               A(i, 2) * B(2, j);
The code to achieve this is:
// Inner loop dot-product
template <int k>
struct Dot
{
	template <typename MA, typename MB>
	static float Do(const MA& A, const MB& B, int i, int j)
	{
		// From last entry to first, find product and add to
		// previous
		return A(i, k – 1) * B(k – 1, j) +
			Dot<k – 1>::Do(A, B, i, j);
	}
};

// Specialisation to terminate the loop
template <>
struct Dot<0>
{
	template <typename MA, typename MB>
	static float Do(const MA&, const MB&, int, int)
	{
		// No more entries to multiply
		return 0;
	}
};

// Same matrix multiplication function with the inner loop
// now gone
template <int M, int N, int P>
Matrix<M, P> Multiply2(const Matrix<M, N>& A, const Matrix<N, P>& B)
{
	Matrix<M , P> result;

	for (int i = 0; i < M; i++)
	{
		for (int j = 0; j < P; j++)
			result(i, j) = Dot<N>::Do(A, B, i, j);
	}

	return result;
}
This generates more efficient code in release:
004011F0  push        ecx
004011F1  fld         dword ptr [ecx]
004011F3  xor         edx,edx
004011F5  fld         dword ptr [ecx+4]
004011F8  fld         dword ptr [ecx+8]
004011FB  mov         ecx,dword ptr [esp+8]
004011FF  fldz
00401201  add         ecx,8

00401204  fld         dword ptr [ecx-8]
00401207  add         edx,1
0040120A  fmul        st,st(4)
0040120C  add         ecx,0Ch
0040120F  cmp         edx,3
00401212  fadd        st,st(1)
00401214  fstp        dword ptr [esp]
00401217  fld         dword ptr [esp]
0040121A  fld         dword ptr [ecx-10h]
0040121D  fmul        st,st(4)
0040121F  faddp       st(1),st
00401221  fstp        dword ptr [esp]
00401224  fld         dword ptr [esp]
00401227  fld         dword ptr [ecx-0Ch]
0040122A  fmul        st,st(3)
0040122C  faddp       st(1),st
0040122E  fstp        dword ptr [eax+edx*4-4]
00401232  jl          Multiply2<float,3,3,1>+14h (401204h)

00401234  fstp        st(3)
00401236  fstp        st(1)
00401238  fstp        st(0)
0040123A  fstp        st(0)
0040123C  pop         ecx
0040123D  ret
The prologue and epilogue are larger but they're comparatively unimportant. The inner loop is smaller, has less memory reads that are less complex, and more arithmetic is being performed on the FPU stack. It seems the for-loop and expression optimisation of the compiler is too generic to compete with a specifically crafted loop-unroller.
It's worth noting that the runtime version of this recursive algorithm physically has to branch to check for zero as the incoming counter value; this prevents it from being inlined and makes the code inefficient (4 function calls to a function that branches each time). This is implemented in the example code.
So all's fine, right? We're feeling brave and thinking about attempting to unroll the entire loop. A look at the generated code in the debug build should persuade you otherwise. No functions are inlined, every function generated by the template pre-processor is stored in code taking up valuable executable space, even though there's very little difference between them. The code is far slower than the debug version of the original multiplier and in a project where such functions are created regularly it can easily get out of hand.
This is perhaps no a problem on PC, but code like this on consoles can add up to kill your ability to debug your game. Good quality generated code for your release builds is important, but more important is very good quality generated code for your debug builds.
The conclusion seems to be that generative code should only be used in release builds while the more generic versions should be used in debug builds. But you have to ask yourself, is the increased maintenance really worth it for such a small gain? Especially considering any inner loops where SIMD-able operations are being performed will already be marked for low level assembler optimisation, making the program wide benefits from optimisation pretty minimal.
I would put that answer at a no and defer to using the original multiplication function, which the compiler does a good job of optimising anyway. I would even go so far as saying that generative programming should not be used for algorithm optmisation as I have yet to see a convincing case of its benefits of speed against maintenance and usability, in more than just a release build.
The results are pretty good however, as an example of what you can achieve with templates in C++. Taking it a bit further we can get:
// Inner column loop generator
template <int N, int P, int j>
struct Inner
{
	template <typename MR, typename MA, typename MB>
	static void Do(MR& result, const MA& A, const MB& B)
	{
		result(i, j – 1) = Dot<N>::Do(A, B, i, j – 1);
		Inner<N, P, j – 1>::Do(result, A, B, i);
	}
};

// Termination for the inner column loop
template <int N, int P>
struct Inner<N, P, 0>
{
	template <typename MR, typename MA, typename MB>
	static void Do(MR&, const MA&, const MB&) { }
};

// Outer row loop generator
template <int N, int P, int i>
struct Outer2
{
	template <typename MR, typename MA, typename MB>
	static void Do(MR& result, const MA& A, const MB& B)
	{
		Inner<N, P, P>::Do(result, A, B, i – 1);
		Outer2<N, P, i – 1>::Do(result, A, B);
	}
};

// Termination for the outer row loop
template <int N, int P>
struct Outer2<N, P, 0>
{
	template <typename MR, typename MA, typename MB>
	static void Do(MR&, const MA&, const MB&) { }
};

// Matrix multiplication function with full loop unrolling
template <int M, int N, int P>
Matrix<M, P> Multiply2(const Matrix<M, N>& A, const Matrix<N, P>& B)
{
	Matrix<M, P> result;
	Outer2<N, P, M>::Do(result, A, B);
	return result;
}
That is the fully unrolled version. The code it generates for matrix/vector multiplication is quite nice:
00401240  push        ecx
00401241  fld         dword ptr [ecx+18h]
00401244  fmul        dword ptr [eax]
00401246  fldz
00401248  fadd        st(1),st
0040124A  fxch        st(1)
0040124C  fstp        dword ptr [esp]
0040124F  fld         dword ptr [esp]
00401252  fld         dword ptr [ecx+1Ch]
00401255  fmul        dword ptr [eax+4]
00401258  faddp       st(1),st
0040125A  fstp        dword ptr [esp]
0040125D  fld         dword ptr [esp]
00401260  fld         dword ptr [ecx+20h]
00401263  fmul        dword ptr [eax+8]
00401266  faddp       st(1),st
00401268  fstp        dword ptr [edx+8]
0040126B  fld         dword ptr [ecx+0Ch]
0040126E  fmul        dword ptr [eax]
00401270  fadd        st,st(1)
00401272  fstp        dword ptr [esp]
00401275  fld         dword ptr [esp]
00401278  fld         dword ptr [ecx+10h]
0040127B  fmul        dword ptr [eax+4]
0040127E  faddp       st(1),st
00401280  fstp        dword ptr [esp]
00401283  fld         dword ptr [esp]
00401286  fld         dword ptr [ecx+14h]
00401289  fmul        dword ptr [eax+8]
0040128C  faddp       st(1),st
0040128E  fstp        dword ptr [edx+4]
00401291  fld         dword ptr [ecx]
00401293  fmul        dword ptr [eax]
00401295  faddp       st(1),st
00401297  fstp        dword ptr [esp]
0040129A  fld         dword ptr [esp]
0040129D  fld         dword ptr [ecx+4]
004012A0  fmul        dword ptr [eax+4]
004012A3  faddp       st(1),st
004012A5  fstp        dword ptr [esp]
004012A8  fld         dword ptr [esp]
004012AB  fld         dword ptr [ecx+8]
004012AE  fmul        dword ptr [eax+8]
004012B1  faddp       st(1),st
004012B3  fstp        dword ptr [edx]
004012B5  pop         ecx
004012B6  ret
The matrix/matrix multiplication is unrolled similarly but not completely. There are two function calls but everything else is unrolled. The compiler is being pretty clever about how it weighs code size against fast code.
The debug code, however, is a horror to behold.